Technical debt on a website: how to recognise it and regain control of maintenance
Learn how to recognise technical debt on a website, measure its maintenance cost, and prioritise actions before it blocks your future developments.
Sur cette page7 sections
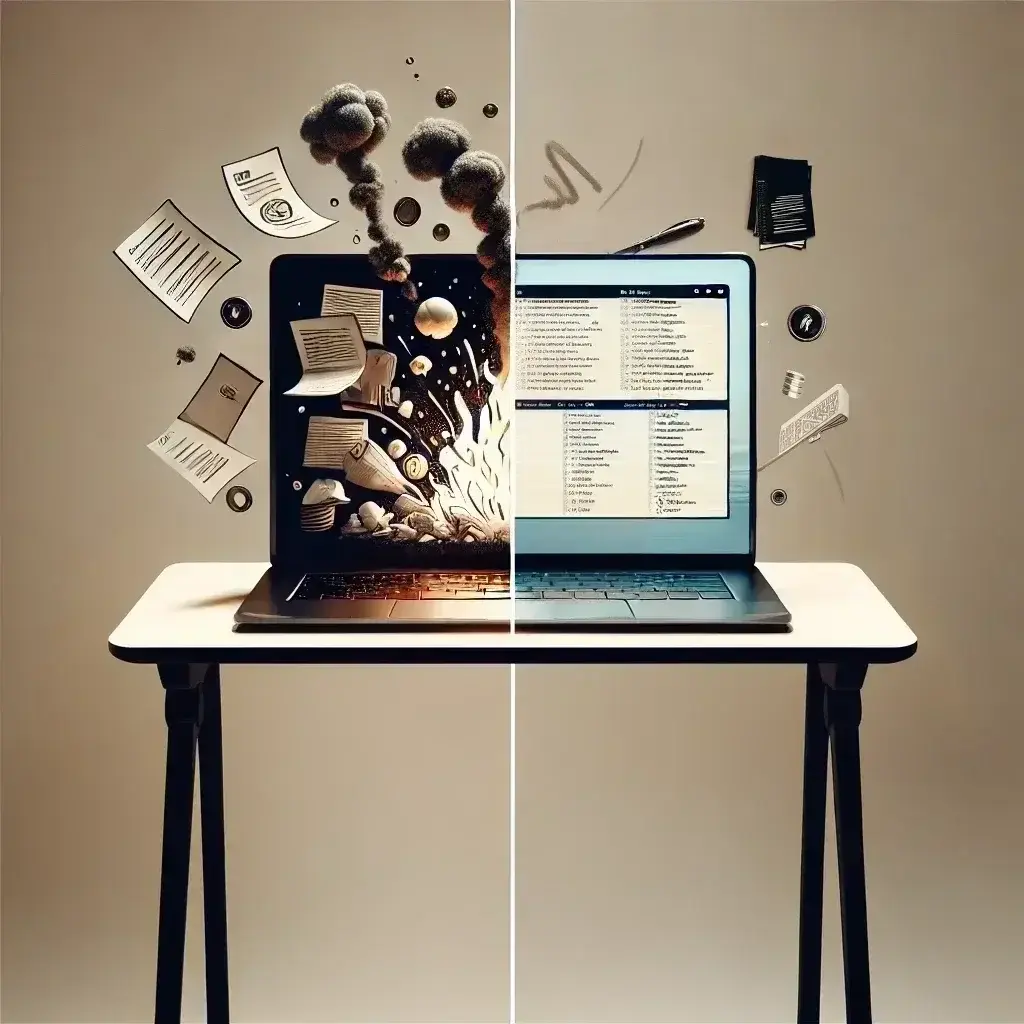
A website can continue to function while becoming increasingly difficult to maintain. A small change then requires a workaround, an update becomes risky, and every new development adds to an already fragile system. This is often a sign of technical debt that progressively weighs down web maintenance.
Technical debt is not reserved for large projects or custom-developed sites. It can appear on a no-code site, in an installation heavy with plugins, or in code that no one dares to touch anymore. The question is therefore not just about which tool or web architecture was used to create the site, but understanding how much effort is actually required to keep it reliable and allow it to evolve.
A quick choice is not automatically a mistake. Using a simple solution to launch a business can be perfectly reasonable. Debt appears when this solution is no longer suitable, is extended with patches, or when no one knows how to properly take over the subject.
The cost is not always visible on an invoice. It manifests as research time, additional testing, hard-to-reproduce errors, dependence on a specific person, or a development that one prefers to postpone. It is this maintenance cost, more than the age of the site, that allows debt to be identified.
No-code is not technical debt in itself. Like any solution, it can remain suitable for a simple and well-defined need. The risk appears when the tool's limits are masked by an accumulation of hacks or when it becomes impossible to evolve the site without depending on a very specific workflow.
The signal to watch for is not the number of tools itself. It is the fact that each addition makes the next one more delicate, or that the site can no longer evolve without following a succession of specific manipulations.
When versions diverge, several generations of solutions coexist, or a dependency no longer has an obvious replacement, the time required for a request increases. A task that used to take a few minutes now requires researching context, checking side effects, and performing several tests. This progressive increase in maintenance time is a particularly useful indicator.
The riskiest case is that of an abandoned site: unavailable provider, incomplete access, poorly identified hosting, lack of verified backups, or no one capable of explaining the choices made. Even if the site seems stable, it becomes difficult to assess what will happen during the next update or the next business request.
The right diagnosis involves documenting each workaround: the need covered, the service involved, the person maintaining it, and the effect of a failure. This view allows for a distinction between a reasonable adaptation and a dependency that has become a blocker.
You must check what each plugin actually provides, if it is still compatible with the rest of the stack, and if an alternative exists. Keeping a plugin just because it is already installed can cost more than a prepared and tested replacement.
Before rewriting, it is useful to evaluate the existing code quality and identify critical paths and the most modified areas. Minimal documentation, a few targeted tests, and the removal of duplications can sometimes significantly reduce risk without rebuilding the entire site.
You need to find the domain name, hosting, admin accounts, connected services, backups, and the paths that generate leads or sales. Without this inventory, any intervention starts with a risk.
Tracking this effort over several requests allows you to see a trend. If every development requires more verification for an equivalent result, debt is likely weighing on the project. This measurement also helps avoid a decision based on an isolated impression.
Maintenance then becomes a steering tool. It is not just for repairing: it allows for a conscious choice of what should be kept, simplified, or replaced.
The decision must compare the cost of continuing to maintain the existing setup with that of a clearer foundation. Pour approfondir ce choix, consultez l’article Website redesign: 7 signs it's time to change. The subject is complementary: here, we start from the cost and legibility of maintenance; the dedicated article details the broader signals that can justify a redesign.
The goal is not to have a site with zero compromises. The goal is to know these compromises, measure their cost, and not let maintenance become a series of gambles. L’article Website maintenance: what does webmaster support really cover? présente les trois dimensions de cet accompagnement et prolonge ce diagnostic par la question du suivi dans le temps.
Start by mapping the existing setup, protecting essential paths, and addressing recurring causes. You can then calmly decide whether to continue simplifying, evolve the base, or start over on a more maintainable foundation.
Technical debt is not reserved for large projects or custom-developed sites. It can appear on a no-code site, in an installation heavy with plugins, or in code that no one dares to touch anymore. The question is therefore not just about which tool or web architecture was used to create the site, but understanding how much effort is actually required to keep it reliable and allow it to evolve.
Technical debt, in simple terms
Technical debt refers to the future cost of decisions made to go faster, bypass a difficulty, or postpone an improvement. Like financial debt, it can be useful if it is known, tracked, and repaid. It becomes problematic when it accumulates without being measured.A quick choice is not automatically a mistake. Using a simple solution to launch a business can be perfectly reasonable. Debt appears when this solution is no longer suitable, is extended with patches, or when no one knows how to properly take over the subject.
A shortcut that is useful at the start can become a constraint
A module added without documentation, a dependency whose update is postponed, a rule copied in several places, or a makeshift connection between two tools can solve an immediate problem. Later, these decisions combine. A change that seemed isolated then affects several parts of the site.The cost is not always visible on an invoice. It manifests as research time, additional testing, hard-to-reproduce errors, dependence on a specific person, or a development that one prefers to postpone. It is this maintenance cost, more than the age of the site, that allows debt to be identified.
What technical debt is not
An old site is not necessarily poorly maintained. Conversely, a recent site can already be fragile if it was built in a hurry, without documentation or follow-up. A one-off failure is also not enough to draw a conclusion: you have to see if the problem recurs, if it is understood, and if its fix creates new workarounds.No-code is not technical debt in itself. Like any solution, it can remain suitable for a simple and well-defined need. The risk appears when the tool's limits are masked by an accumulation of hacks or when it becomes impossible to evolve the site without depending on a very specific workflow.
Signs that debt is setting in
Technical debt is rarely recognised by a single symptom. Instead, it reveals itself through a series of small, repeating frictions that eventually slow down the site or the business.- every modification requires a workaround or the intervention of a single person;
- plugins, libraries, or services are no longer maintained and replacing them seems risky;
- the same bug returns because the root cause was not addressed;
- the technical stack has thickened over time with additions, without an inventory or a clear owner;
- backups, access, procedures, or tests do not allow for a confident return to a functional state.
When the exception becomes the method
On a no-code site, the first workaround may seem harmless: an external integration to add a feature, a script to fix a behaviour, then another service to link the two. The site provides the expected service, but its operation gradually depends on an assembly that is difficult to explain and reproduce.The signal to watch for is not the number of tools itself. It is the fact that each addition makes the next one more delicate, or that the site can no longer evolve without following a succession of specific manipulations.
A changing stack, rising maintenance time
A site rarely evolves all at once. Its CMS, plugins, hosting, third-party services, or front-end components change at different times. This gradual evolution is normal, but it must remain legible.When versions diverge, several generations of solutions coexist, or a dependency no longer has an obvious replacement, the time required for a request increases. A task that used to take a few minutes now requires researching context, checking side effects, and performing several tests. This progressive increase in maintenance time is a particularly useful indicator.
A site that no one wants to touch anymore
Difficult-to-maintain code is not just complex code. It is also code where rules are not explained, names do not clarify roles, or previous fixes have left unexpected side effects.The riskiest case is that of an abandoned site: unavailable provider, incomplete access, poorly identified hosting, lack of verified backups, or no one capable of explaining the choices made. Even if the site seems stable, it becomes difficult to assess what will happen during the next update or the next business request.
Four common situations to recognise
A no-code site with workarounds
The site started with a simple promise, then needs multiplied. To keep the initial tool, automations, scripts, third-party services, or manual manipulations were added. The result may look fine on screen, but no one always knows which brick is essential and which can be removed.The right diagnosis involves documenting each workaround: the need covered, the service involved, the person maintaining it, and the effect of a failure. This view allows for a distinction between a reasonable adaptation and a dependency that has become a blocker.
Numerous unmaintained plugins
An unmaintained plugin is not necessarily problematic the day it stops being updated. The risk increases when the site depends on several plugins in this situation, especially if they are involved in forms, accounts, payment, SEO, or security.You must check what each plugin actually provides, if it is still compatible with the rest of the stack, and if an alternative exists. Keeping a plugin just because it is already installed can cost more than a prepared and tested replacement.
Code that is no longer maintainable
In unmaintainable code, the problem is not that no modification is possible. It is that a trivial modification becomes unpredictable. Rules are duplicated, responsibilities mixed, exceptions numerous, and tests insufficient to know what has been broken.Before rewriting, it is useful to evaluate the existing code quality and identify critical paths and the most modified areas. Minimal documentation, a few targeted tests, and the removal of duplications can sometimes significantly reduce risk without rebuilding the entire site.
An abandoned site
A site can be abandoned without being offline. It continues to display pages, but its access is not centralised, its backup is not verified, and its operation relies on unwritten habits. The first step is then not to add a feature: it is to regain visibility over what exists.You need to find the domain name, hosting, admin accounts, connected services, backups, and the paths that generate leads or sales. Without this inventory, any intervention starts with a risk.
Diagnosing without deciding too quickly to rebuild everything
A useful diagnosis does not start with the choice of a new tool. It starts with a snapshot of the existing setup and the use cases that matter to the business. The goal is to know what works, what slows down requests, and what exposes the site to disproportionate risk.- inventory the stack: CMS or framework, hosting, plugins, third-party services, versions, and access;
- link each component to its role, its maintenance level, and a responsible person;
- walk through essential paths: display, forms, contact, client area, or other business actions;
- note recurring incidents, workarounds, and the time actually spent on each type of request;
- compare options: fix locally, simplify progressively, replace a component, or prepare a rebuild.
Measuring the actual maintenance effort
Maintenance time is not just the time spent writing code. It includes finding access, understanding context, preparing a backup, testing before and after intervention, fixing side effects, and documenting what will make it easier to do again.Tracking this effort over several requests allows you to see a trend. If every development requires more verification for an equivalent result, debt is likely weighing on the project. This measurement also helps avoid a decision based on an isolated impression.
Distinguishing a local problem from a structural one
A failing form can be a local incident. If fixing it requires modifying several layers without documentation, or if the same situation repeats on other functions, the issue becomes structural. This distinction is important: fixing a symptom is sometimes the right answer, but it should not be confused with upgrading the foundation.Prioritising to regain control
Reducing technical debt does not mean stopping business to clean up the entire project. It is about first addressing what threatens the operation, security, scalability, or understanding of the site.- secure access, backups, and the workflows the business depends on;
- fix recurring errors and truly blocking dependencies;
- simplify workarounds that add the most risk for the least value;
- document decisions, versions, and rollback procedures;
- reserve comfort and presentation improvements for stages where they do not mask a structural problem.
Reducing debt without creating a new layer
Every fix should leave the site a bit more understandable than before: a dependency removed, a rule consolidated, an access documented, a test added, or a procedure clarified. Conversely, a new workaround can give the impression of progress while increasing the cost of the next request.Maintenance then becomes a steering tool. It is not just for repairing: it allows for a conscious choice of what should be kept, simplified, or replaced.
When does a rebuild become relevant?
A rebuild is worth considering when local fixes no longer reduce risk, when every development reproduces the same difficulties, when essential dependencies are no longer maintained, or when the site can no longer support the business's needs. The age of the site or the trendiness of a new stack are not enough on their own.The decision must compare the cost of continuing to maintain the existing setup with that of a clearer foundation. Pour approfondir ce choix, consultez l’article Website redesign: 7 signs it's time to change. The subject is complementary: here, we start from the cost and legibility of maintenance; the dedicated article details the broader signals that can justify a redesign.
Maintenance as a way to stay in control
Useful maintenance combines technical monitoring, correction, and evolution. It keeps track of the stack, verifies backups, monitors dependencies, and turns repeated requests into lasting improvements. It also gives the manager concrete information: what is urgent, what can wait, and what deserves a structural decision.The goal is not to have a site with zero compromises. The goal is to know these compromises, measure their cost, and not let maintenance become a series of gambles. L’article Website maintenance: what does webmaster support really cover? présente les trois dimensions de cet accompagnement et prolonge ce diagnostic par la question du suivi dans le temps.
Conclusion: regaining control before the emergency
Technical debt on a website is identified when workarounds multiply, the stack becomes illegible, and maintenance time increases for identical results. It does not automatically doom the site to a rebuild: it first requires a diagnosis, an effort measurement, and clear prioritisation.Start by mapping the existing setup, protecting essential paths, and addressing recurring causes. You can then calmly decide whether to continue simplifying, evolve the base, or start over on a more maintainable foundation.